Finished! Looks like this project is out of data at the moment!
New Subject Sets!
This project has been built using the Zooniverse Project Builder but is not yet an official Zooniverse project. Queries and issues relating to this project directed at the Zooniverse Team may not receive any response.
Help us create training data for a Book Annotation Classification Engine
Learn moreYou can do real research by clicking to get started here!
Zooniverse Talk
Chat with the research team and other volunteers!
Book Annotation Classification Statistics
View more statsAll Time Stats
Active Stats
Active stats provide information about currently active workflows and subjects.
Message from the researcher
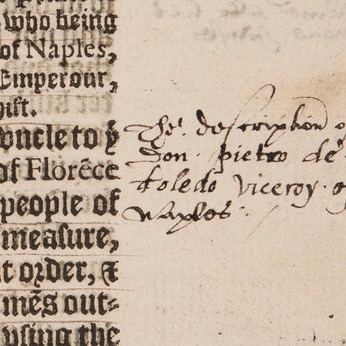
Why do we care about finding annotations? Annotations and other marks are traces left behind by previous readers and owners. Through these markings, we can better understand how readers in the past have used their books or interpreted their contents.
kirschbombeAbout Book Annotation Classification
The UCLA Collections Lab needs your help to generate training data for the Book Annotation Classification Engine project, a machine-learning experiment to identify and classify annotations in large collections of digitized printed books.
In Phase I, we are collecting data to identify pages that contain annotations and asking users to tag and classify these annotation. The data collected will serve as training data for the machine-learning experiments to develop a tool that researchers can use to discover annotated pages in IIIF-hosted digital collections. All resulting data will be made publicly available via our UCLA Collections Lab GitHub space.